AI-Readiness Data Assessments · P&C Insurance
Know if your data can deliver the AI you were promised.
In six weeks, we grade every system your AI use case depends on and show you what will break it, before you fund the pilot.
FNOL Intake · AI Consumability
This is where an FNOL triage pilot dies.
Loss descriptions arrive as free text and scanned PDFs. A triage model has nothing structured to read at first notice.
Why It Matters
60% of P&C insurers are stuck in AI pilot mode. Here's how it happens.
Source: Capgemini, The Intelligence Era in P&C, 2026. The pilot below is illustrative.
Anatomy of a Failed Pilot
- 1
Week 6
The demo wins.
Trained on a curated set of historical claims, cleaned by hand, the FNOL triage model scores 92% in the steering committee demo. Funding approved.
- 2
Go-live
Production data arrives.
- 3
Week 14
Accuracy collapses.
- 4
Week 22
Quietly shelved.
Week 6 · 1 of 4
The demo wins.
Trained on a curated set of historical claims, cleaned by hand, the FNOL triage model scores 92% in the steering committee demo. Funding approved.
FNOL triage model · accuracy
87%The Plan · What We Provide
Three steps. Six weeks.
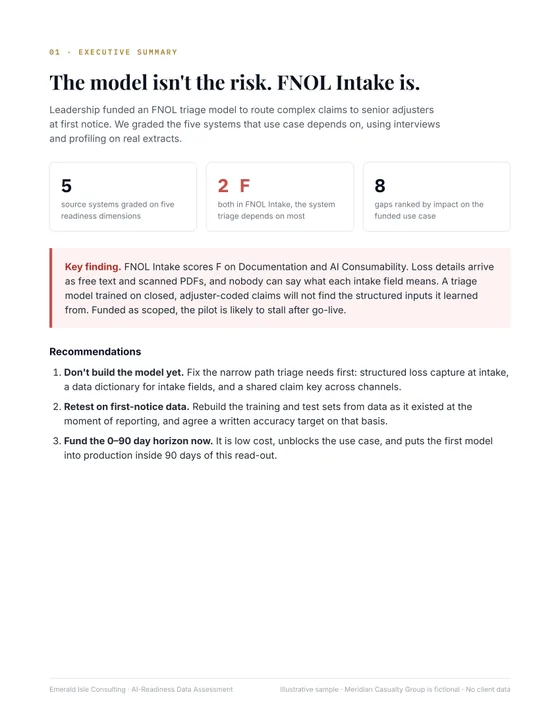
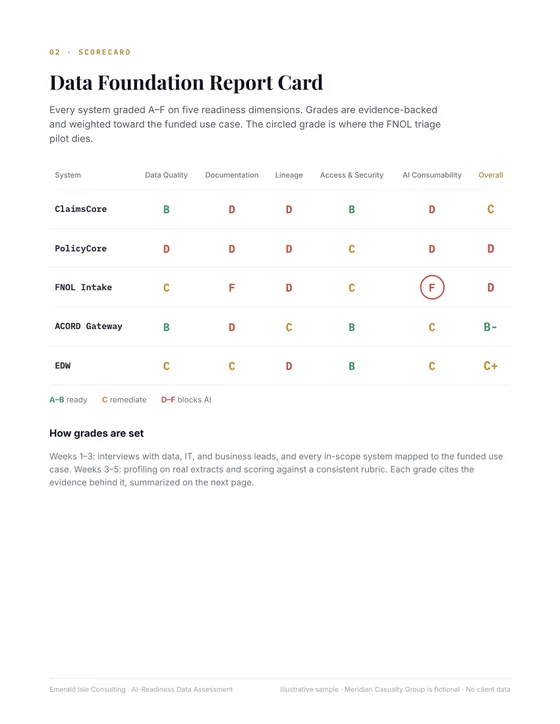
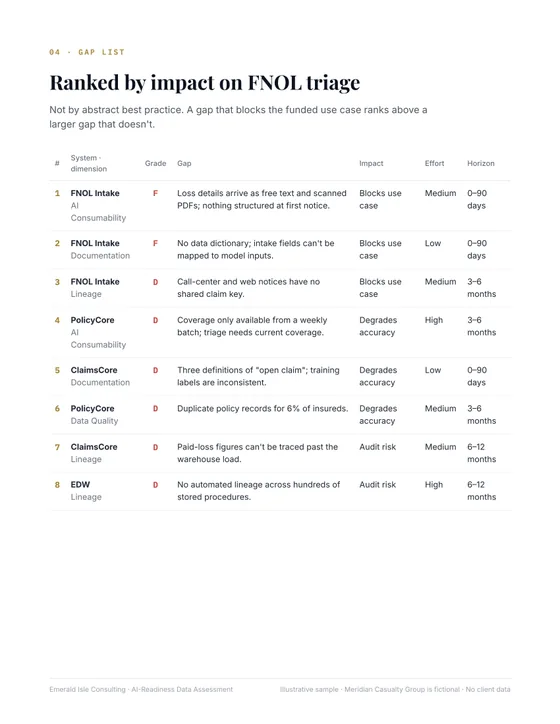
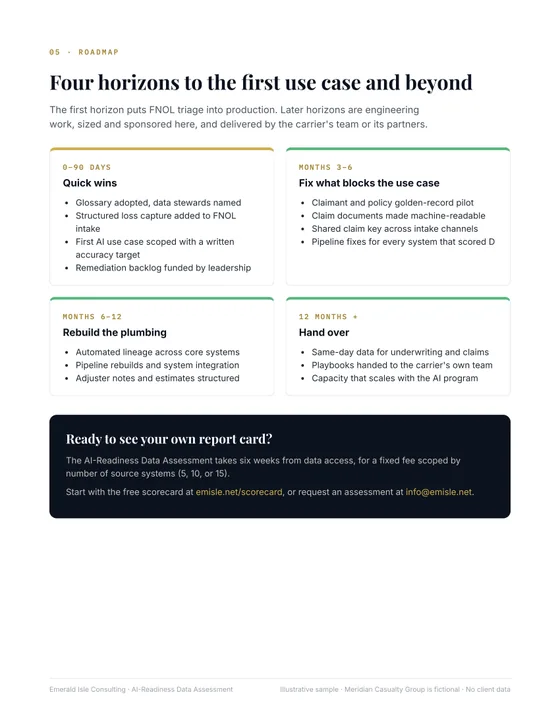
You get a scorecard, a ranked fix list and a roadmap, built from your own systems' data, not opinions. Below are real pages from a sample read-out for a fictional P&C carrier.
Weeks 1–3
1 · Map
Every system your use case depends on, mapped with the people who run it.
WhySo we assess only the systems your use case touches, not your whole data estate.
Weeks 3–5
2 · Grade
Real extracts profiled; each system graded A–F on five dimensions.
WhyInterviews tell you what people believe about the data. Profiling shows what it actually is.
Week 6
3 · Decide
Ranked fix list and a four-horizon roadmap. Yours to act on.
WhySo leadership can make the call with evidence, not opinions.
What It's Worth
Six weeks now, or six months later.
The same AI initiative, two ways. The assessment costs a fixed fee and six weeks. Skipping it can cost the whole pilot budget, and you still won't know why it failed.
Fund the pilot and hope
6 months, then shelved- Wk 0Pilot funded
- Wk 8Demo wins
- Wk 12Go-live
- Wk 19Accuracy collapses
- Wk 26Shelved
Budget spent, team burned out, and nobody agrees why it failed. The next vendor meets the same data.
Assess first
~19 weeks to production- Wk 0Data access
- Wk 6Graded read-out
- Wk 12Blockers fixed
- Wk 19First use case live
Blockers found and fixed before the build, a sized budget leadership trusts, and one use case in production.
Illustrative timelines. “Assess first” assumes the Applied AI Build follows the read-out.
You Leave With
A go / no-go decision backed by evidence, a budget leadership can defend, and a 90-day path to your first use case in production.
Why Us
We've built what we grade.
Before we graded data platforms, we built them. That's why our grades hold up. Two engagements, anonymized:
85%
Less time finding underwriting answers
Insurance knowledge search
10 days → near real time
Claims reporting latency
Healthcare claims data platform
+23%
Fraud detection accuracy
Healthcare claims data platform
Know before you fund the pilot.
Six weeks and a fixed fee, scoped by the number of systems your use case depends on.
See exactly what's included